No. 04of 22LandmarkResearch
Role-specific AI agents whose work is checked before it is certified
AI E (AI Employees)
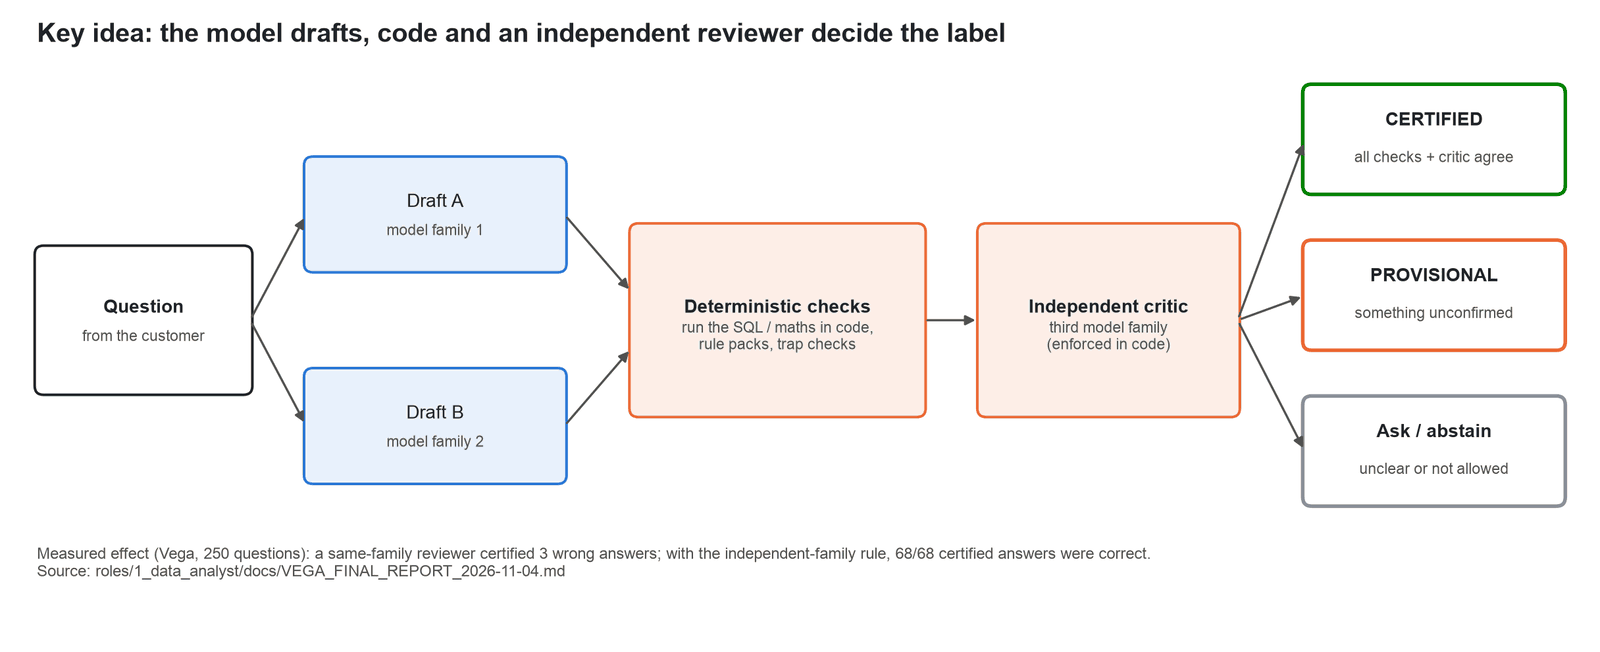
Five AI employees for finance, data analysis, HR, QA and DevOps on one shared runtime. The language model only drafts: numbers and rules come from deterministic engines, and an answer is marked certified only when those checks pass and a reviewer model from a different family agrees.
- When
- Oct – Nov 2026
- Status
- Built
Progress
Progress70%
All five employees, the website, the security layer and the evaluation suites exist and have run. It runs on a local machine only, payments are a demo wallet, and no model is fine-tuned.
What comes next
- Re-grade the HR employee's results and save them, so they can be quoted.
- Add a human or rival-tool baseline, and a blind set for the data analyst.
- Host it publicly once rate limiting, a content security policy and two-factor sign-in are in.
246 / 250
analyst questions answered correctly by Vega, the data analyst (98.4%)
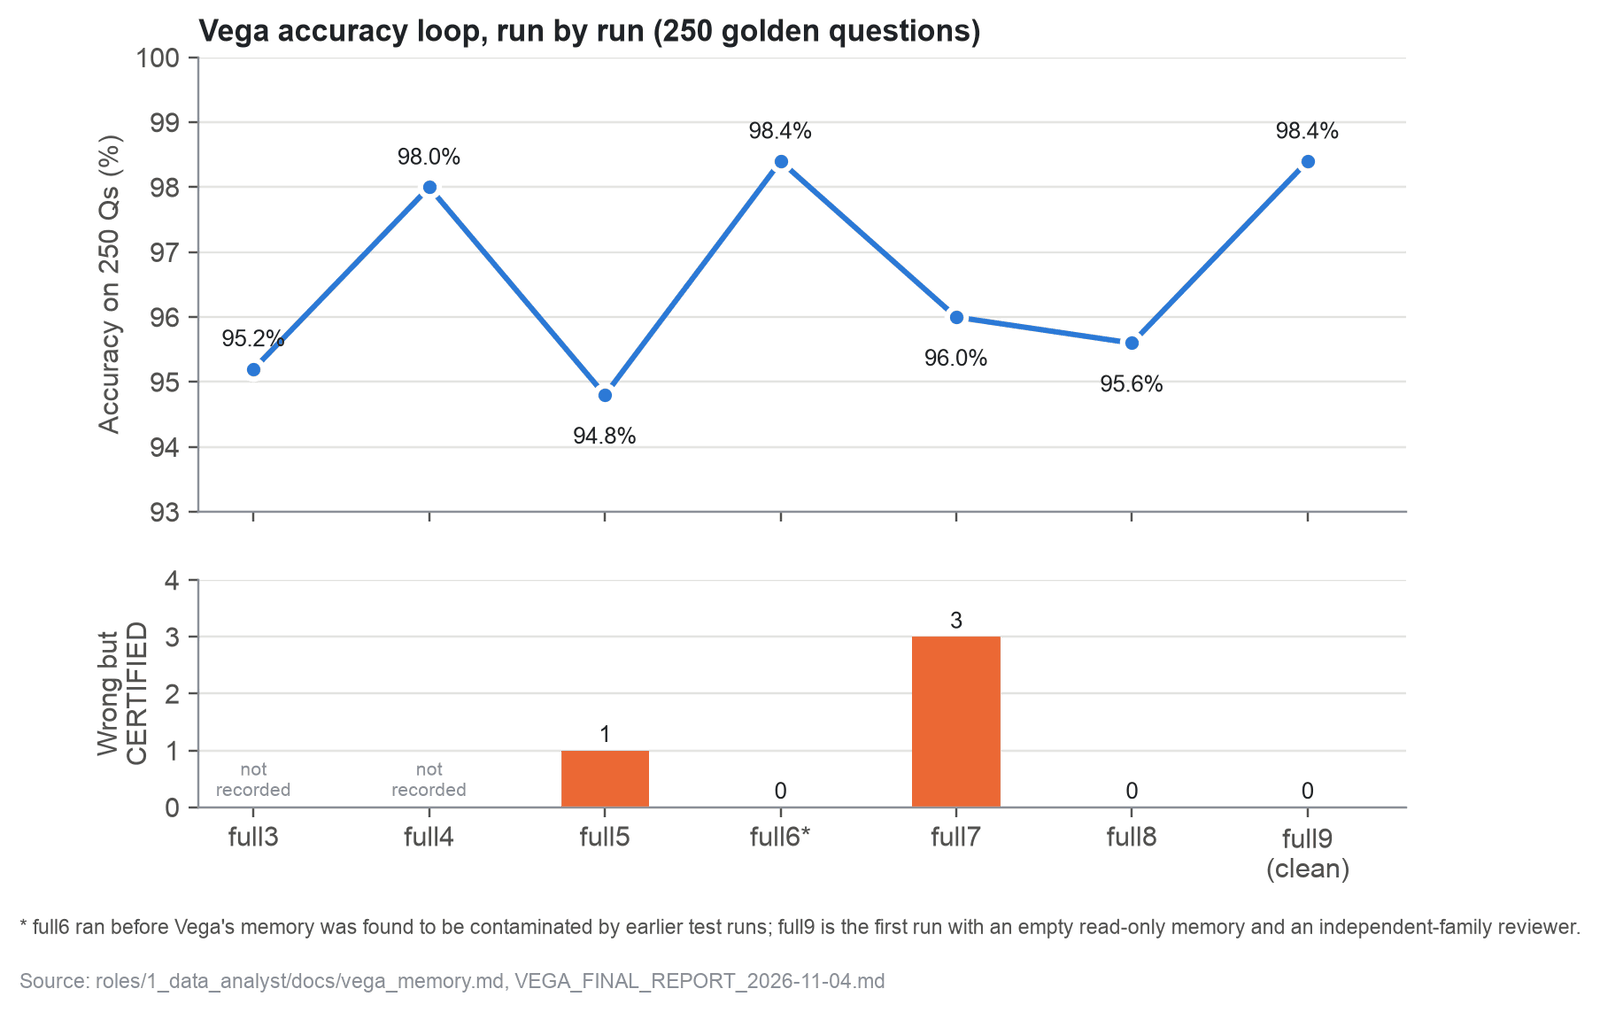
On its own 250-question evaluation set, after several rounds of iteration on that set. Vega has no blind set yet.
Evaluation run output (data analyst, results/full9.log and full9.jsonl)Verified. Backed by a file or public page that has been checked.Evaluation run output (data analyst, results/full9.log and full9.jsonl) — Read in the project audit of 13 November 2026.0 of 68
certified answers that were wrong, in that same run
Only 68 of the 250 answers earned the certified label. The claim is about those 68.
Evaluation run output (data analyst, results/full9.log and full9.jsonl)Verified. Backed by a file or public page that has been checked.Evaluation run output (data analyst, results/full9.log and full9.jsonl) — Read in the project audit of 13 November 2026.0 of 554
planted-bad finance documents wrongly marked ready by Aurex
Finance accuracy scorecard (finance ops, results/accuracy_scorecard.md)Verified. Backed by a file or public page that has been checked.Finance accuracy scorecard (finance ops, results/accuracy_scorecard.md) — Read in the project audit of 13 November 2026.56/56 → 16/20
planted bugs found by Verix: on its development set, then on blind projects
The blind run also made 1 false claim. Tuned scores do not fully carry over to unseen work.
QA scorecards (SCORECARD_development.json and SCORECARD_blind.json)Verified. Backed by a file or public page that has been checked.QA scorecards (SCORECARD_development.json and SCORECARD_blind.json) — Read in the project audit of 13 November 2026.12 / 12
direct prompt-injection tests blocked by the security layer
One small test set, run on 8 November 2026. In the same run, 79 of 80 pieces of other roles' work were refused.
Security test report (security/reports/tests-20261108.md)Verified. Backed by a file or public page that has been checked.Security test report (security/reports/tests-20261108.md) — Read in the project audit of 13 November 2026.8.0s
month-end close on 507,745 ledger lines
A load test of the deterministic finance engines on one workstation. No model calls are involved.
Finance load-test output (load_test_2026-10-27.json)Verified. Backed by a file or public page that has been checked.Finance load-test output (load_test_2026-10-27.json) — Read in the project audit of 13 November 2026.Exhibit 01 · Walk-through
Watch one job
Step 01
Assign the work
The request is in plain language: how many customers in the Northwind sample database have never placed an order? List them, then send the report to Slack. Vega, the data analyst, starts: a plan, SQL drafted by two models, a read-only run, checks, a critic, a report.
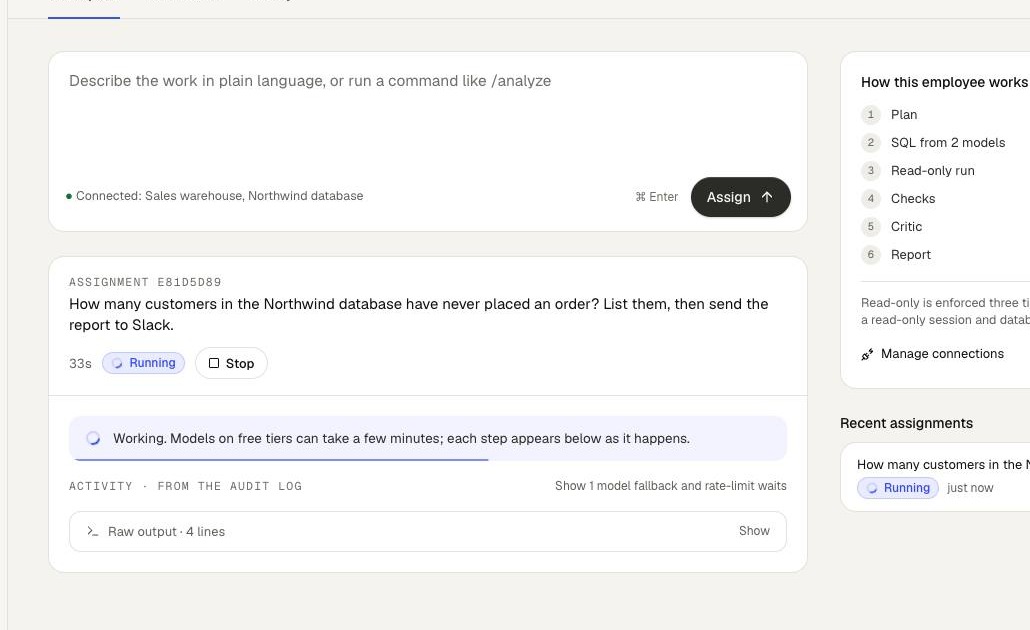
33 seconds in. The job is running. Step 02
It stops and asks
Sending to Slack changes something outside the system, so the job pauses on an approval card that shows exactly what would be sent. A person chooses Deny or Approve. Nothing risky happens without that choice.
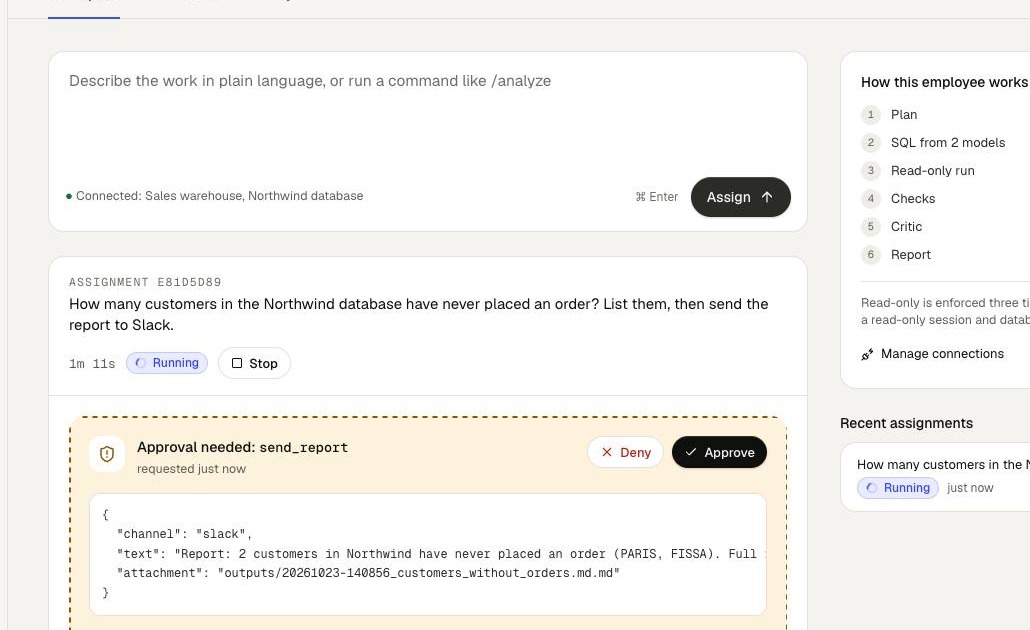
The approval gate, with the payload in full. Step 03
The answer, with the decision on record
Here the reviewer pressed Deny. The job still finishes, in 1 minute 22 seconds, and the answer arrives with the denial logged above it: two customers have never placed an order.
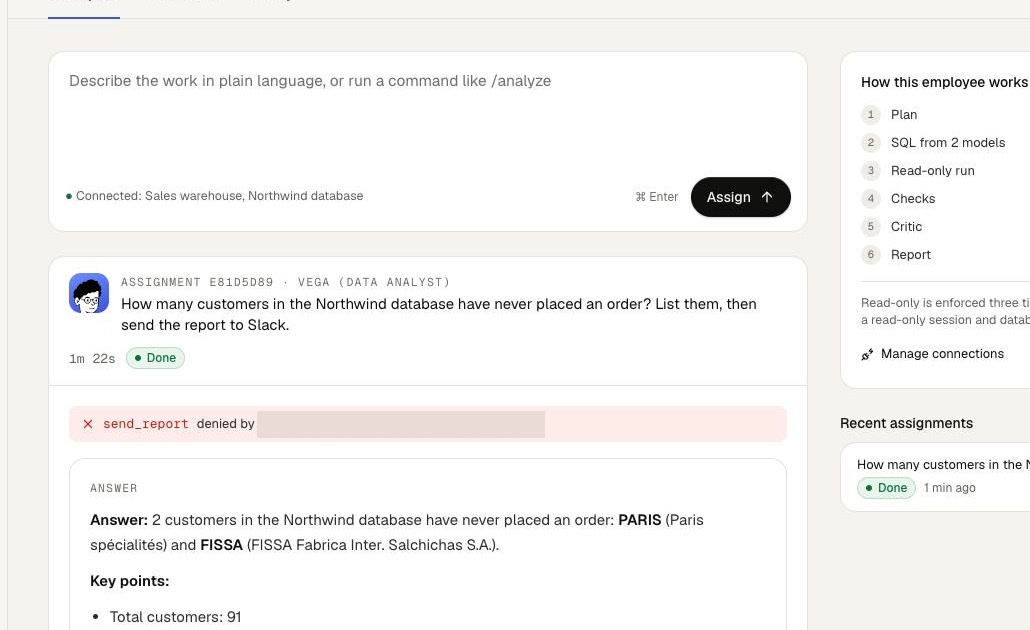
Done. The test account's address in the red bar is masked.
Exhibit 02 · Compare
Tuned versus blind
Development set
56 / 56
Verix, the QA employee, found every planted bug in the projects it was developed against, with no false positives, and triaged 24 of 24 CI failures. These are the cases it was tuned on.
Blind, never seen
16 / 20
On projects it had never seen, Verix found 16 of 20 bugs and made 1 false claim; its PR review caught 19 of 20. Argus, the DevOps employee, found 20 of 25 issues in a blind cluster sweep, with no false findings on 8 clean objects.
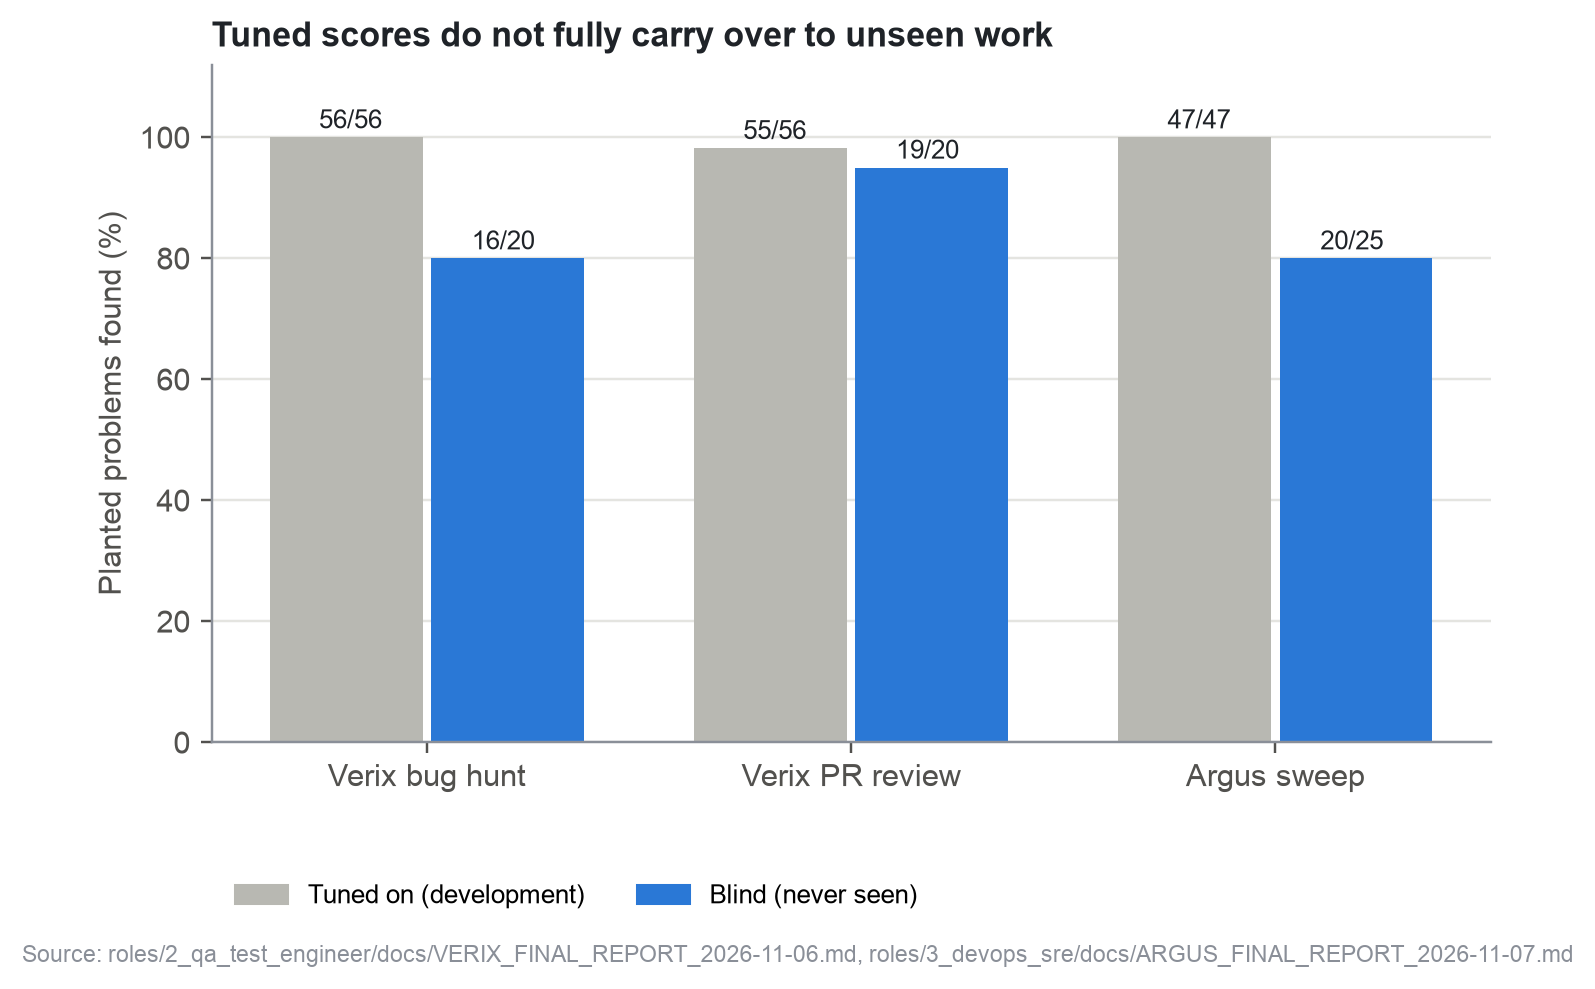
The two sets of numbers are always shown together: tuned scores do not fully carry over to unseen work. Vega, the data analyst, has no blind set yet.
Exhibit 03 · Scorecard
Every verified result
Run outputs read in the project audit of 13 November 2026. Tuned and blind results are listed together. There is no human or rival-tool baseline yet.
| Measure | Result | Note | Source |
|---|---|---|---|
| Vega (data analyst): 250 analyst questions across 10 domains | 246 / 250 (98.4%) | Its own evaluation set, after several rounds of iteration on it. No blind set exists for Vega. | evals/results/full9.log, full9.jsonl |
| Vega: trap questions | 70 / 70 | evals/results/full9.log, full9.jsonl | |
| Vega: wrong answers marked CERTIFIED | 0 | 68 of the 250 answers were certified, and all 68 were correct. | evals/results/full9.log, full9.jsonl |
| Vega: statistical tasks | 30 / 30 | evals/results/s2_full7.log | |
| Aurex (finance): 63 golden finance questions | 63 / 63 | With Qwen3.6-27B. 62 / 63 after a later build; the miss passed on a re-run. | evals/results/2026-10-27_ovhcloud_Qwen3.6-27B_final.json and final2 |
| Aurex: planted-bad documents wrongly marked ready | 0 of 554 | evals/results/accuracy_scorecard.md | |
| Aurex: SEC EDGAR 10-K rebuilds and bank-statement files | 11 / 11 companies, 13 / 13 files | evals/results/accuracy_scorecard.md | |
| Aurex load test: invoice validation | 5,000 invoices at 349.5 per second | 400 / 400 recall, 0 / 4,600 false alarms. | evals/results/load_test_2026-10-27.json |
| Aurex load test: month-end close | 507,745 ledger lines in 8.0 s | A 50,000-line bank reconciliation took 8.6 s. Deterministic engines on one workstation. | evals/results/load_test_2026-10-27.json |
| Verix (QA): development set | 56 / 56 planted bugs | 0 false positives; CI triage 24 / 24. This is the set it was tuned on. | evals/results/SCORECARD_development.json |
| Verix: blind projects | 16 / 20 bug hunt, 19 / 20 PR review | 1 false claim in the bug hunt. | evals/results/SCORECARD_blind.json |
| Argus (DevOps): blind sweep | 20 / 25 issues found | 0 false findings on 8 clean objects, in 1.6 s. | evals/blind_1/grade_blind.json |
| Nexa (HR): accent fairness in voice interviews | 0.0 score spread across 5 accents | About 5.9% speech-to-text error. Nexa's question-answering results are not quoted: no graded result file was saved. | interviews/evals/results/accents.json |
| Security: own-role work accepted | 30 / 30 | security/reports/tests-20261108.md | |
| Security: other roles' work refused | 79 / 80 | security/reports/tests-20261108.md | |
| Security: direct injection blocked | 12 / 12 | One small test set, 8 November 2026. | security/reports/tests-20261108.md |
| Security: data-loss checks | 5 / 5 | security/reports/tests-20261108.md | |
| End-to-end customer journey | 18 / 18 answer checks, 14 / 14 steps | 8.2 minutes in all. | outputs/20261023-0122_customer_journey_FINAL/journey.json |
01
What it is
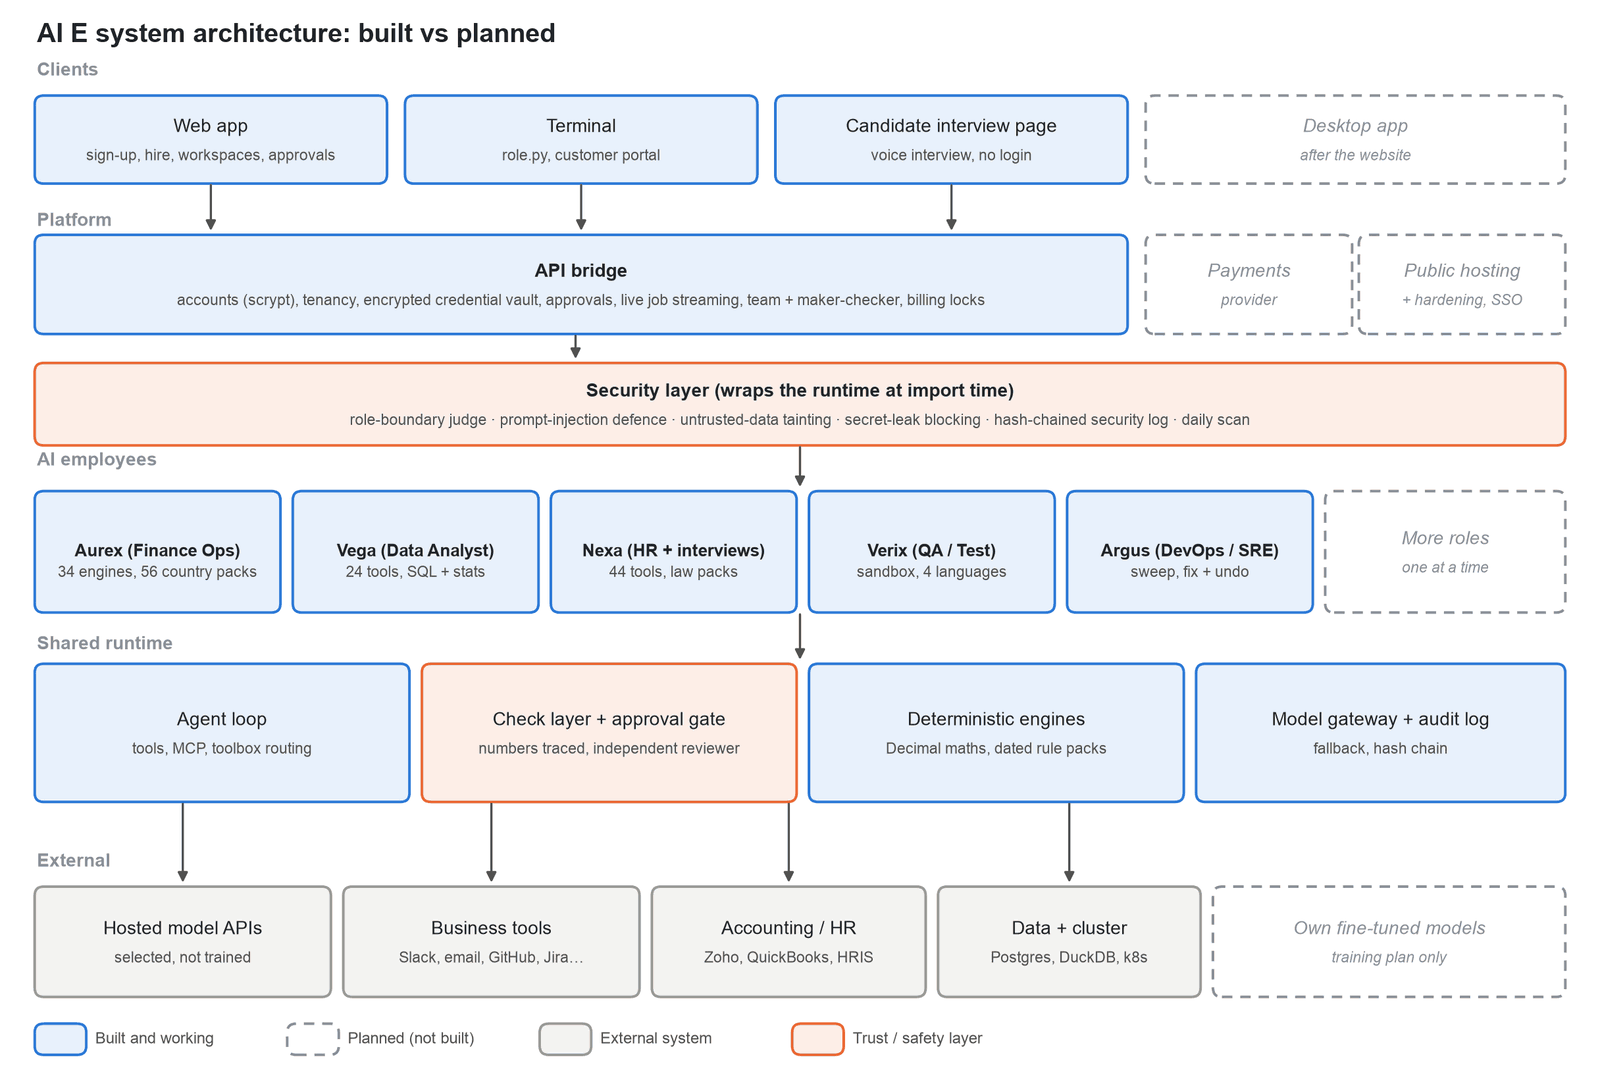
A company "hires" an AI employee for a role, connects its own tools, assigns work in plain language and approves anything risky. Five employees exist: Aurex for finance operations, Vega for data analysis, Nexa for HR, Verix for QA and testing, and Argus for DevOps. It was built between 22 October and 9 November 2026 as a startup project, and it runs on a local machine.
02
The hard part
A language model will state a wrong number with complete confidence. So here the model only drafts. Numbers, tax, banking and labor-law facts come from deterministic engines and dated rule packs. An answer is labeled CERTIFIED only when the deterministic checks pass and a reviewer model from a different model family agrees; otherwise it is PROVISIONAL, or the employee asks. The project's own runs show why the family rule matters: a reviewer from the same family certified three wrong answers, and under the independent-family rule all 68 certified answers were correct.
03
What was built
A shared agent runtime: a model gateway with provider fallback, the agent loop, an approval gate, a check layer, an MCP client, a Docker sandbox with no network, an AES-256-GCM credential vault and a hash-chained audit log. A security layer wraps it: a role-boundary judge, prompt-injection defense and data-loss blocking. The five employees sit on top, each with its own tools, from 30-plus finance engines and 56 country tax packs to a 70-rule cluster sweep with dry-run and undo. The website is Next.js 16 with 20 routes and streams jobs live through a FastAPI bridge. In all, about 80,000 lines of Python and 6,000 of TypeScript. The models are hosted and swappable; none is fine-tuned.
04
What was measured
On its own 250-question set, after several rounds of iteration, Vega answered 246 correctly, passed 70 of 70 trap questions, and certified 68 answers, all of them correct. Aurex marked none of 554 planted-bad finance documents as ready, and closed a month of 507,745 ledger lines in 8.0 seconds. Scores drop on unseen work, and the project reports both: Verix found 56 of 56 planted bugs on its development set and 16 of 20 on blind projects, with one false claim. Argus found 20 of 25 issues in a blind sweep. The security layer blocked 12 of 12 direct injection tests and refused 79 of 80 pieces of out-of-role work.
05
What it does not claim
It is not hosted publicly, payments are a demo wallet, and no model has been fine-tuned. Vega has no blind test set yet, so its 98.4% is a tuned figure. The HR employee's question-answering results are not quoted, because no graded result file was saved. There is no human or rival-tool baseline. The project's paper, report and deck are drafts and are not linked.
Figures
One question
The answer is on this page. Get it right and it goes in your passport on the map.
Challenge· stamped
Vega, the data analyst, answered 246 of 250 questions correctly. How many of its answers earned the CERTIFIED label?
68. An answer is certified only when the deterministic checks pass and a reviewer from a different model family agrees, and all 68 certified answers were correct. Source: the run's output files (full9), read in the project audit of 13 November 2026.
Show the answer
68. 68. An answer is certified only when the deterministic checks pass and a reviewer from a different model family agrees, and all 68 certified answers were correct. Source: the run's output files (full9), read in the project audit of 13 November 2026.
- Stack
- Python
- FastAPI
- Next.js 16
- React 19
- Tailwind 4
- PostgreSQL
- DuckDB
- Docker
- Kubernetes (kind)
- Prometheus
- Model Context Protocol (MCP)
- Whisper
- ONNX Runtime
- Hosted and local LLMs (OpenRouter, Groq, Gemini, Ollama)